Architecting the Enterprise Private LLM: A Blueprint for Infrastructure, Sizing, and High-Performance Networking
As data sovereignty, regulatory compliance (such as GDPR, HIPAA, and financial frameworks), and intellectual property protection take center stage, enterprises are shifting rapidly from public cloud APIs to private Large Language Model (LLM) deployments. Operating a private LLM means your sensitive corporate data never leaves your infrastructure perimeter.
However, building an internal LLM stack is an exercise in complex systems engineering rather than traditional application hosting. This guide details the essential considerations, parameter sizing requirements, dataset parameters, and the high-performance hardware fabric required—anchored by industry standards from NVIDIA and Arista Networks.
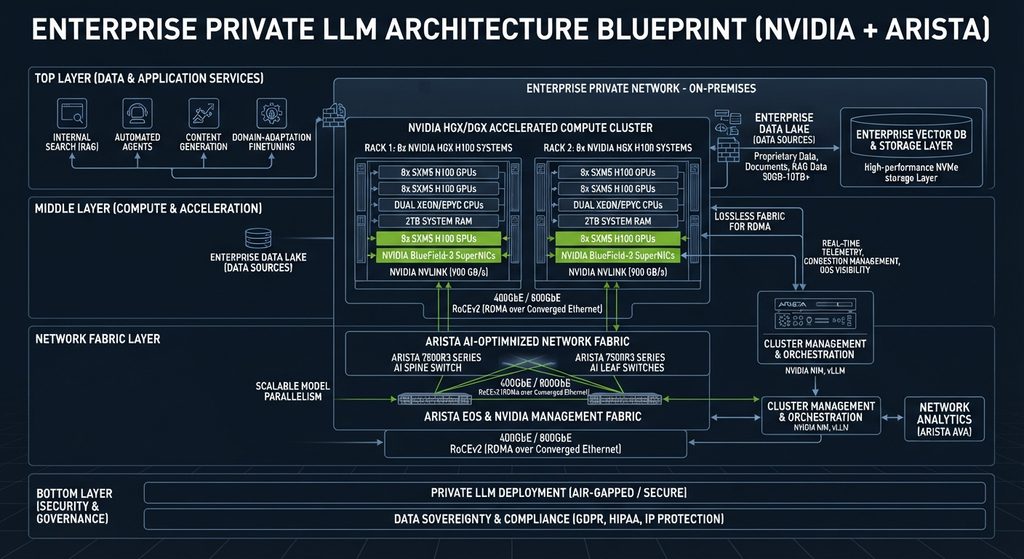
Private LLM architecture for enterprise infrastructure, sizing, and high-performance networking.
Defining the Scope: Parameters, Applications, and Datasets
Before procuring hardware, you must clearly scope the functional requirements of your private AI ecosystem.
Model Parameters & Sizing
- Small-to-Medium Models (7B to 13B parameters):Ideal for text summarization, classification, localized routing, and standard Retrieval-Augmented Generation (RAG) tasks. They require lower VRAM footprints and can easily fit on single-server multi-GPU configurations.
- Large Foundation Models (70B+ parameters): Necessary for advanced reasoning, multi-step agentic workflows, and complex coding tasks. A 70B parameter model in FP16 precision requires roughly 140 GB of VRAM just for the model weights, necessitating multi-GPU and multi-node architectures.
Applications & Workloads
- Inference vs. Fine-Tuning: Most enterprises start with secure inference combined with a vector database for RAG. However, if you plan to domain-adapt or instruction-fine-tune open-weights models (like Llama or NVIDIA Nemotron) on proprietary datasets, your infrastructure must accommodate heavy gradient updates, driving up memory and interconnect requirements.
- Concurrency and Quality of Service (QoS): Calculate your peak Concurrent Users (CCU) and target Time-to-First-Token (TTFT). High-concurrency enterprise applications require specialized serving runtimes like NVIDIA NIM (Inference Microservice) or vLLM with continuous batching to optimize throughput.
Datasets and Storage Footprint
- RAG Vector Stores: RAG datasets typically scale from 50 GB to over 10 TB of internal documentation (Confluence, SharePoint, codebases). This requires high-performance NVMe storage for fast embedding lookups.
- Checkpointing for Fine-Tuning: Training or heavy fine-tuning creates massive checkpoint files (weights, optimizer states, and metadata exceeding terabytes). Storage subsystems must support high throughput (e.g., writing multi-terabyte checkpoints in under 60 seconds) to prevent expensive GPU starvation.
Compute and Sizing Requirements (The NVIDIA Foundation)
GPU and server configurations dictate whether your AI initiative runs smoothly or bogs down under latency bottlenecks.
- GPU Architecture (SXM vs. PCIe): For production inference and fine-tuning of 70B+ models, avoid standard PCIe-based consumer or enterprise cards due to bandwidth restrictions. Instead, deploy NVIDIA HGX systems powered by SXM5 GPUs (such as H100 or newer generations). NVLink provides dedicated, point-to-point GPU-to-GPU bandwidth up to 900 GB/s, eliminating communication stalls during tensor-parallel execution.
- Server Node Sizing: A standard enterprise production building block is an 8-way GPU node (e.g., NVIDIA DGX/HGX architecture) paired with high-core-count enterprise CPUs (e.g., dual Intel Xeon or AMD EPYC), minimum 1 TB to 2 TB of system RAM, and high-speed local NVMe caching layers for rapid dataset ingestion.
The Network Fabric: Bridging NVIDIA Compute with Arista Networks
In a distributed LLM cluster, the network is the computer. When models scale across multiple nodes, GPUs spend significant time synchronizing weights and activations via collective operations (AllReduce, All-to-All). If the network lags, expensive GPUs sit idle.
This is where an integrated architecture combining NVIDIA SuperNICs/BlueField and Arista Networks shines:
High-Speed Link Speeds and Protocols
- Interconnect Bandwidth: Enterprise private LLM clusters require 400GbE or 800GbE rail-optimized network designs.
- RoCEv2 (RDMA over Converged Ethernet): Rather than proprietary fabrics, modern enterprise AI architectures leverage RoCEv2 running on standard, high-performance Ethernet switches. This enables low-latency, lossless data transmission required for distributed model parallel training and high-throughput inference routing.
Architectural Integration: NVIDIA & Arista
- Arista Etherlink Platforms: Built on advanced merchant silicon (such as Broadcom Tomahawk and Jericho families integrated via Arista EOS), Arista’s AI-optimized switches feature deep buffers and dynamic load balancing to eliminate “elephant flow” congestion. This ensures deterministic, low-latency traffic paths essential for minimizing AI Job Completion Time (JCT).
- Unified Telemetry and Control: Managing disparate AI silos is a primary source of infrastructure misconfiguration. Through joint frameworks, Arista EOS-based AI agents can communicate directly with NVIDIA BlueField-3 SuperNICs and host servers. This provides a single pane of glass to monitor congestion, validate end-to-end Quality of Service (QoS), and automatically debug packet-drop issues across both the compute NICs and the network fabric.
- Autonomous Operations (Arista AVA): Utilizing Autonomous Virtual Assist (AVA) tools allows network administrators to run real-time telemetry analysis, ensuring that the heavy telemetry data generated by thousands of GPU traffic streams can be proactively managed and secured.
Conclusion: Building Secure and Scalable Private LLM Infrastructure
Designing an effective private LLM architecture requires more than selecting powerful GPUs or deploying large AI models.
Instead, enterprises must create a balanced infrastructure that integrates accelerated computing, high-performance networking, efficient storage, and strong data governance.
First, organizations should identify their AI use cases, model requirements, and expected workloads. This helps determine whether smaller models can meet business needs or whether larger foundation models are necessary.
Next, infrastructure architects must evaluate GPU memory, server capacity, and model serving requirements. Technologies such as NVIDIA HGX and NVLink can support demanding workloads that benefit from high-bandwidth GPU communication.
Furthermore, network performance becomes increasingly important as AI clusters expand across multiple servers. Arista Ethernet fabrics, combined with properly engineered RoCEv2 connectivity, can support high-throughput communication for distributed AI workloads.
However, infrastructure performance alone does not guarantee successful deployment. Organizations must also address data protection, access control, operational visibility, scalability, and total cost of ownership.
Therefore, enterprises should validate their architecture through workload benchmarking, capacity planning, and security assessments before making major infrastructure investments.
Ultimately, successful private LLM deployment depends on aligning AI infrastructure capabilities with business requirements.
By taking a structured approach to model sizing, GPU selection, storage, and networking, organizations can build more secure, reliable, and scalable private AI environments.
Need Expert Guidance for Your Enterprise AI Infrastructure?
Building a private LLM environment involves complex decisions across compute, networking, storage, and security.
TREZBON TECHNOLOGIES provides enterprise IT infrastructure consulting, network architecture, and system integration expertise to help organizations plan and evaluate their technology environments.
Whether your organization is assessing GPU networking requirements, high-performance Ethernet fabrics, or infrastructure modernization, our team can help you evaluate the architecture and integration requirements.
Discuss your enterprise AI infrastructure requirements with TREZBON TECHNOLOGIES.
🌐 https://www.trezbon.com/contact
For more technical insights into private LLM architecture, AI infrastructure, and enterprise networking, explore NETWORK BACHELOR.
Kubernetes for AI/ML Workloads: GPU Scheduling & MLOps Guide
NVIDIA GPU Worker Nodes on Kubernetes: Installation & Cluster Setup
Kubernetes GPU Monitoring: Prometheus, Grafana & DCGM Guide
About Author

Muhammad Marakkoottathil(MM)
Expert in the field of SDN, cloud computing, virtualization, active-active data center design & migration. Passionate about helping organizations to achieve their digital transformation objectives with strong 15+ years of experience in design, deployment, and managing heterogeneous network solutions across the industry verticals. Major Industry Certifications: Cisco CCIE, CCDP, VMware VCAP-NV_DESIGN, TOGAF, ITIL, NUTANIX NCSE, Google Cloud Architect, Azure Fundamentals More info please visit my page @ LinkedIn: https://www.linkedin.com/in/contactmm/