Aviatrix Multicloud Transit: ACE Lessons for Production
Around 5 years ago I have completed the Aviatrix Certified Engineer (ACE) – Multicloud Network Associate when it was talk of the town. It’s tempting to file certifications like this under “resume line item” and move on. But this one is worth writing about, because the material addresses a failure pattern that shows up repeatedly in enterprise multicloud environments — one that’s easy to design your way into without realizing it.
A Common Setup
Picture a typical enterprise multi-site environment: two or more private cloud regions (say, one in the Middle East, one in Europe) connected to an on-premises data center, stitched together with a virtualization overlay like NSX-T Federation and a private WAN circuit like ExpressRoute or Direct Connect.
On paper this looks clean — a hub-and-spoke model where the overlay handles micro-segmentation and the private circuit provides the backbone between sites.
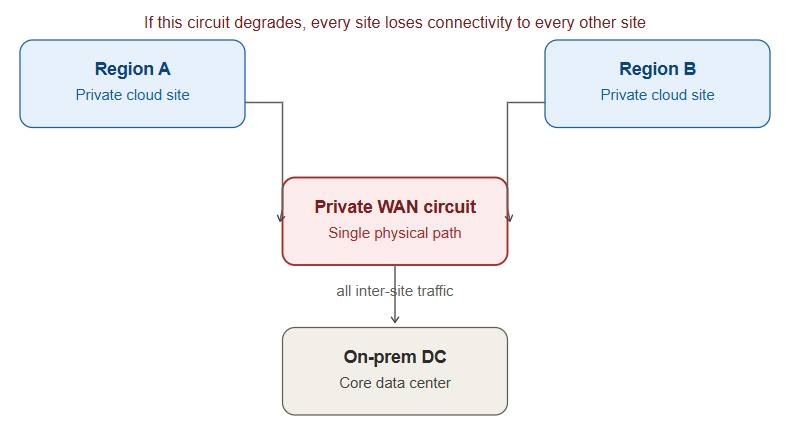
In practice, the private circuit often becomes a single point of architectural dependency. Every cross-site conversation — region-to-region, region-to-on-prem, and eventually region-to-future-region — traverses the same circuit. There’s no independent transit layer; the WAN quietly becomes the topology itself.
The Issue
The problem tends to surface when an organization needs to onboard a new region, usually for a DR expansion or capacity growth. Two things become clear almost immediately:
- Circuit bandwidth caps turn a routing change into a capacity negotiation. Adding a new site isn’t just updating a route table — it’s renegotiating a physical circuit, which can take weeks and is bounded by whatever tier of service is available in that region.
- The overlay’s span is tied to the same physical path. Any degradation or maintenance window on the private circuit doesn’t just slow things down — it takes down the only path for inter-site policy sync and traffic, because there’s no secondary transit fabric independent of the underlay.
Organizations in this position typically have redundancy in compute and storage across sites, but not in the transit layer connecting them. That distinction is easy to miss until it costs a maintenance window that can’t be taken.
The Common (Tactical) Fix
Without a dedicated multicloud transit layer, the typical workaround is tactical rather than architectural:
- Negotiate a secondary circuit on a different peering path as a failover, rather than a true parallel transit fabric
- Tighten overlay sync windows to reduce blast radius during circuit maintenance
- Document the single point of failure explicitly in the DR runbook so it’s a known risk rather than a surprise
This works, but it’s a patch on a design gap — not a fix for the gap itself. It treats the symptom (limited failover) rather than the underlying architecture problem: no cloud-native transit layer decoupled from the underlay.
Where Aviatrix Actually Fits
This is where the ACE material clarifies the gap. Aviatrix’s multicloud transit architecture is built specifically for this scenario:
- A transit fabric that sits above the underlay, meaning any single circuit becomes one of several paths rather than the path. Transit gateways in each cloud/region peer independently of the physical circuit topology.
- Encrypted, high-performance inter-region peering that doesn’t require every packet to traverse a single private circuit — so a maintenance window degrades one path, not the whole fabric.
- Centralized visibility and troubleshooting (CoPilot) across sites, replacing a lot of manual cross-checking between overlay consoles and circuit dashboards during incident response.
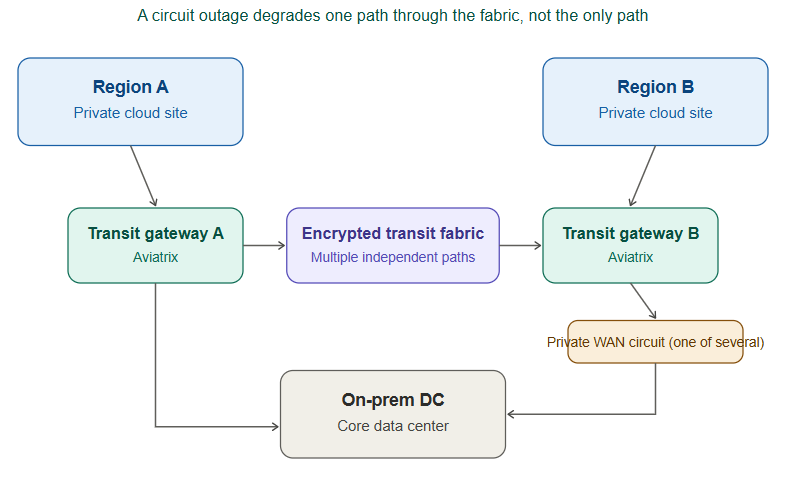
The core lesson: it’s easy to conflate “physical connectivity” with “transit architecture.” A private circuit like ExpressRoute is excellent as an underlay — it is not, by itself, a resilient multicloud transit strategy. A purpose-built transit layer like Aviatrix decouples those two concerns, which is exactly the kind of design principle that’s hard to internalize from documentation alone and much easier to internalize after an incident forces the question.
Conclusion: Building Resilient Multicloud Networks with Aviatrix
The Aviatrix ACE certification offers valuable lessons beyond technical knowledge and professional credentials.
One important lesson is the difference between physical network connectivity and multicloud transit architecture.
Many enterprises invest in redundant computing, storage, and cloud infrastructure. However, they may overlook dependencies within their network connectivity.
As organizations expand across regions, these dependencies can create performance, scalability, and availability challenges.
Therefore, network architects must consider more than bandwidth and basic connectivity.
They should evaluate routing flexibility, network redundancy, encrypted communication, and centralized visibility.
This is where Aviatrix multicloud transit architecture can provide value.
Its transit gateway architecture supports connectivity between cloud environments. Furthermore, encrypted peering and centralized management can simplify certain multicloud networking operations.
However, successful implementation still requires careful planning and testing.
Organizations must evaluate their existing infrastructure, connectivity requirements, and disaster recovery objectives before selecting an architecture.
The Aviatrix ACE certification reinforces these important design principles.
More importantly, it encourages engineers to approach multicloud networking from an architectural perspective rather than focusing only on individual technologies.
Ultimately, a resilient multicloud network depends on more than reliable connections.
It requires a well-designed transit architecture that supports business continuity, operational visibility, and future growth.
For network engineers and cloud architects, this is the real value of connecting certification knowledge with production experience.
Is Your Multicloud Network Ready for Future Growth?
Expanding into new cloud regions should not introduce unnecessary network complexity or unexpected connectivity risks.
However, hidden dependencies, limited redundancy, and inefficient routing can affect business continuity.
Trezbon Technologies helps organizations evaluate enterprise network architectures and identify opportunities to improve connectivity, security, and resilience.
Our consulting approach focuses on understanding your existing infrastructure, business requirements, and technical challenges.
Whether you are planning multicloud expansion, reviewing WAN connectivity, or improving network resilience, our team can help you evaluate the next steps.
Build a Stronger Foundation for Your Multicloud Infrastructure
Talk to Our Experts
Explore our consulting and enterprise networking services:
Frequently Asked Questions About Aviatrix Multicloud Transit
1. What is Aviatrix multicloud transit?
Aviatrix multicloud transit is a networking architecture that connects cloud networks through transit and spoke gateways.
It supports communication between cloud environments and provides capabilities for encrypted connectivity, routing, and centralized network management.
2. What is the Aviatrix ACE certification?
The Aviatrix Certified Engineer (ACE) program provides training in cloud networking and security.
It covers multicloud architecture, transit networking, cloud connectivity, encryption, and operational troubleshooting.
3. Why is multicloud transit architecture important?
Multicloud transit architecture helps organizations manage connectivity between cloud regions and environments.
Furthermore, a well-designed transit network can support scalability, operational visibility, and network resilience.
4. Can Aviatrix replace ExpressRoute or Direct Connect?
Aviatrix and private connectivity services serve different architectural purposes.
ExpressRoute and Direct Connect provide private connectivity between supported environments.
In contrast, Aviatrix provides a transit architecture that can use available connectivity paths.
Therefore, organizations should evaluate how these technologies work together.
5. How can organizations improve multicloud network resilience?
Organizations should identify network dependencies and evaluate alternative connectivity paths.
Additionally, they should implement appropriate redundancy, monitor network performance, and regularly test failover procedures.
These measures can help reduce the impact of connectivity failures.
Distributed LLM Inference: GPU Networking, vLLM & llm-d

AI-Powered Firewall Troubleshooting: GraphRAG, Neo4j, RAG & Network Automation
Agentic AI Capacity Planning: Why vLLM Changes the Model
About Author

abhishek
Cloud Platform Lead and AI Infrastructure Architect at e& enterprise, with 12+ years in data center, virtualization, security and AI infrastructure. I design and build private cloud and sovereign AI platforms, working with VMware (NSX-T, vSphere, vSAN, HCX, AVS, SRM), Kubernetes, Terraform and GPU inference infrastructure for LLMs. Previously served Networkers Home (CCIE instructor, trained around 50 CCIEs), VCE/EMC2, Cisco, VMware and Arista across TAC, consulting, design and training. Certifications: CCIE#48639 (Data Center and R&S), VCIX-DCV and NV, CKA, NVIDIA AI Infrastructure, Azure Solutions Architect Expert, Terraform Associate, Palo Alto PCNSE. LinkedIn: https://www.linkedin.com/in/abhishekkunal51/