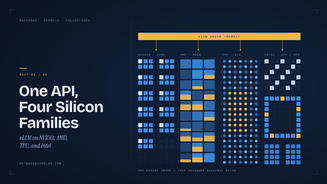
Compare vLLM multi-hardware inference across NVIDIA, AMD, Google TPU and Intel for performance, portability, cost and enterprise AI infrastructure. Today, vLLM multi-hardware inference can run across NVIDIA GPUs, AMD Instinct accelerators, Google TPUs, and Intel hardware
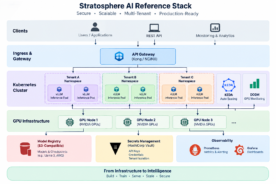
Build practical AI infrastructure skills across 12 hands-on stages covering Kubernetes, NVIDIA GPUs, LLM inference, autoscaling, observability, security and more.