Learn how to add NVIDIA GPU worker nodes to Kubernetes, install containerd and kubeadm, deploy GPU Operator components, validate GPUs, and verify RDMA networking.
Build a Kubernetes cluster for NVIDIA GPU workloads from bare metal. Configure containerd, kubeadm, HA control planes, CNI, and validate cluster readiness.
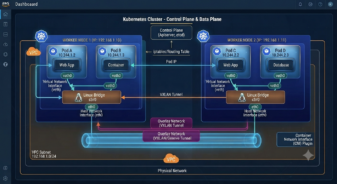
Learn Kubernetes networking fundamentals, including OSI layers, overlay networks, VXLAN, network namespaces, veth pairs, Linux bridges, and pod networking.
The muscle-memory layer: commands, config files, and scripts — for the networking person moving into HPC/AI Ops (Part two of a series — part one: From Jupyter Notebook to InfiniBand Fabric, covering what the ML/LLM team actually hands you before this stage begins.) Knowing what Slurm is and knowing what a Slurm admin does all
A network engineer’s field guide to the other side of the AI infrastructure stack If you’ve spent your career on fabric design and CCIE-grade network builds, the ML/LLM training world looks like a black box wrapped in a black box. A “job” shows up in the Slurm queue, it asks for 8 GPUs across 2
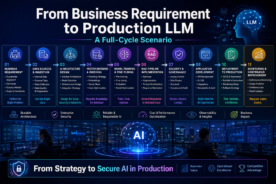
Every production LLM that answers a customer question or automates a workflow passed through the hands of five or six distinct roles before it ever served a single request. Each role hands off a well-defined artifact to the next — and when that handoff is fuzzy, that’s usually where projects stall for months. This post