Private LLM Router: Architecture, Security & Deployment
Introduction: Why Enterprises Need a Private LLM Router
Artificial intelligence is becoming an important part of enterprise applications. Today, organizations use large language models (LLMs) for document analysis, software development, customer support, and business automation.
However, deploying AI applications across multiple models introduces new challenges. For example, organizations must manage data security, model performance, and infrastructure costs. In addition, integrating different AI models can increase operational complexity. Therefore, businesses need a reliable approach to managing these challenges. As a result, a private LLM router can simplify model access and improve infrastructure management.
Businesses must consider data security, infrastructure costs, model performance, and application reliability. In addition, regulated organizations need greater control over how they process sensitive information. For example, financial institutions and healthcare providers must follow strict data protection requirements. Furthermore, they need to protect confidential information from unauthorized access. Therefore, organizations should implement secure data processing and storage practices. As a result, private AI infrastructure can strengthen data security and support regulatory compliance.
Public LLM platforms make model access easier. For example, OpenRouter allows developers to access multiple AI models through a single API. As a result, developers can simplify model integration and reduce the complexity of managing different AI services.
Recently, I explored several public LLM providers, including Claude, OpenRouter, OpenAI, and DeepSeek. Among them, OpenRouter stood out because of its simple approach to managing multiple models. Furthermore, its unified API makes it easier to work with different AI models. Therefore, developers can focus more on building applications rather than managing separate integrations.
However, what happens when an organization cannot send sensitive information to external AI services?
For instance, banks often handle confidential financial information. Similarly, healthcare organizations must protect sensitive patient records. In addition, technology companies may need to keep proprietary source code within their own infrastructure.
Consequently, these organizations may require greater control over AI model deployment and data processing. Therefore, a private LLM router can provide an alternative to public AI services while supporting enterprise security requirements.
This is where a Private LLM Router becomes useful.
A private LLM router provides a single API endpoint for accessing multiple language models hosted within an organization’s infrastructure.
Instead of sending requests to public AI services, applications can communicate directly with locally deployed models. As a result, organizations gain greater control over AI infrastructure and sensitive data.
Furthermore, private LLM deployment allows businesses to manage multiple AI models within their own environments. In addition, it can help organizations strengthen security and simplify model management.
For instance, organizations can integrate the following AI model-serving platforms:
- vLLM for high-performance model serving.
- Ollama for running supported open-weight models.
- NVIDIA NIM for containerized AI inference services.
- Hugging Face Text Generation Inference (TGI) for supported model-serving workloads.
Furthermore, a private routing layer helps teams manage authentication, model selection, request distribution, monitoring, and resource utilization.
In addition, it provides centralized control over multiple AI models. As a result, organizations can simplify model management and improve operational efficiency.
Moreover, developers can access different models through a consistent interface. Therefore, they no longer need to manage every backend separately.
Consequently, development teams can reduce integration complexity and focus on building AI applications.
What Will You Learn in This Guide?
This article explains how to design and build a private LLM router using enterprise infrastructure.
We will explore the core architecture, API gateway, model registry, intelligent routing engine, and provider adapters.
Next, we will examine security controls, Kubernetes deployment, GPU inference, and monitoring.
Finally, we will explore how organizations can extend this architecture into a managed private AI service.
Furthermore, this approach can help businesses deliver secure and reliable AI solutions. In addition, it creates opportunities to offer managed AI services to enterprise customers.
The goal is simple: Build a secure, flexible, and manageable platform for enterprise AI applications.
At the same time, organizations must maintain control over their underlying infrastructure. Therefore, they should prioritize data security, scalability, and operational efficiency.
Ultimately, a well-designed private LLM router can simplify AI infrastructure management while supporting long-term business growth.
Why Not Just Use OpenRouter?
- Data sovereignty: Prompts and completions must never leave your network perimeter
- Compliance: HIPAA, PCI-DSS, SOC2, ISO27001 — data residency requirements forbid external
API calls - Latency control: Sub-50ms routing requirements that external APIs cannot guarantee
- Model customization: Fine-tuned or domain-specific models not on any public registry
- Cost structure: Token pricing at cloud rates vs. amortized GPU hardware cost
- Air-gap requirements: Physically disconnected networks (defense, critical infrastructure)
High-Level Architecture
The private LLM router follows a layered architecture similar to OpenRouter. However, it replaces external dependencies with on-premises or self-hosted alternatives.
As a result, organizations gain greater control over their AI infrastructure and data processing. Furthermore, this approach allows enterprises to manage multiple language models within their own environments.
In addition, each architectural layer performs a specific function. For example, the API gateway manages incoming requests, while the routing engine selects suitable AI models.
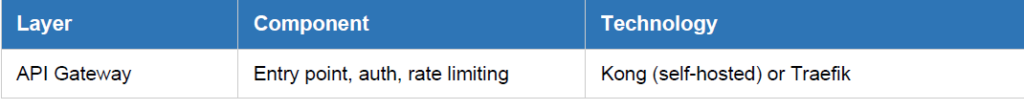
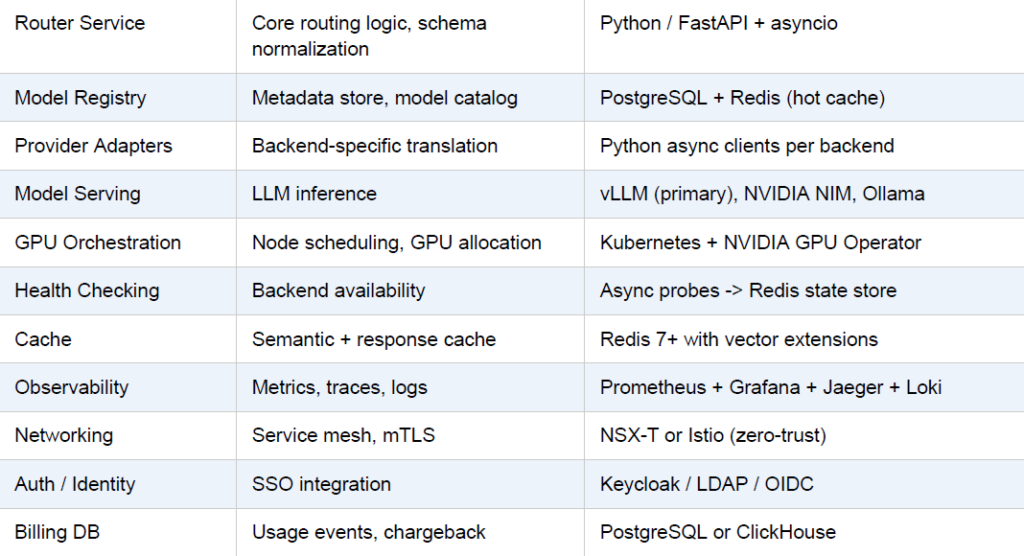
Therefore, organizations can simplify model integration and improve operational efficiency. Ultimately, this architecture provides a flexible foundation for secure and scalable enterprise AI applications. Here is the full stack view:
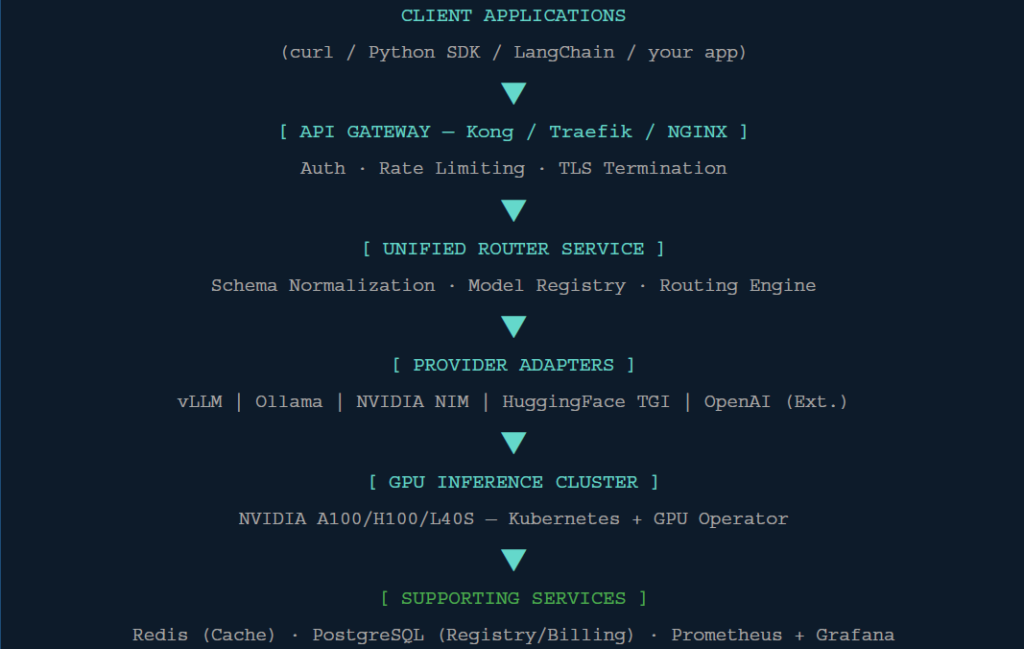
Each layer has a clear responsibility. Requests flow down through the stack and responses bubble back
up — with every hop logged, metered, and observable.
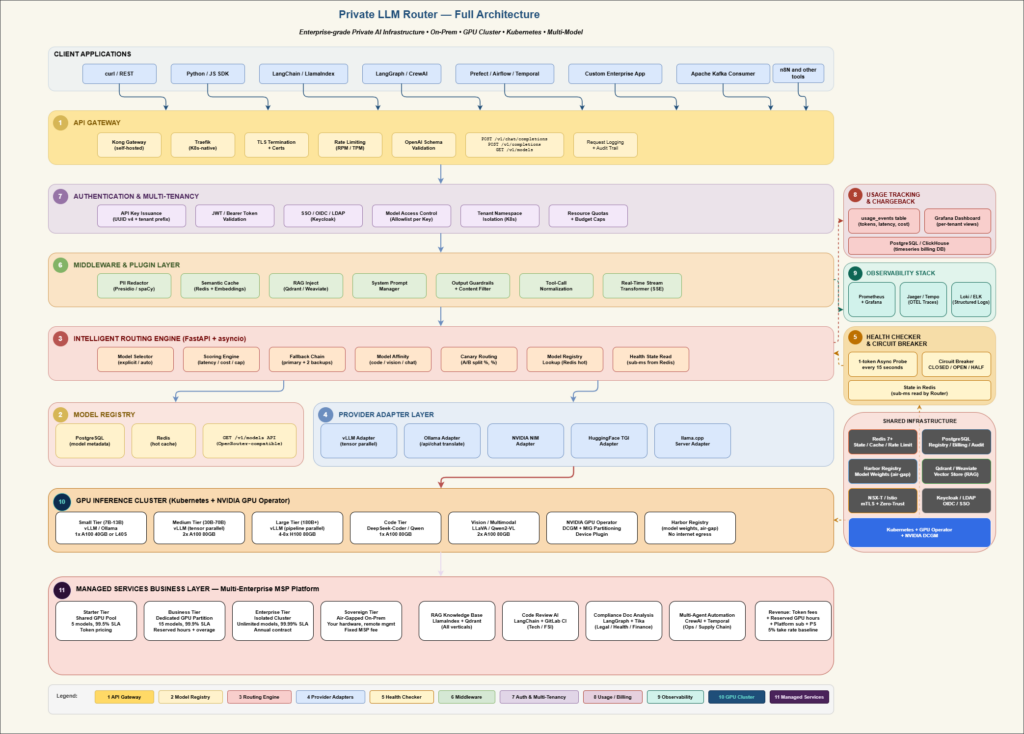
Core Components
- API Gateway
The API Gateway is the single entry point for all client traffic. It handles cross-cutting concerns before
requests even reach your routing logic.
- Kong Gateway (self-hosted): Best-in-class plugin ecosystem. Plugins for JWT, rate limiting,
request transformation, and Prometheus metrics out of the box. - Traefik: Lightweight, Kubernetes-native. Excellent for dynamic routing via IngressRoutes. Lower
operational overhead than Kong. - NGINX + Lua: Maximum control for fine-grained request manipulation at wire speed.
Your gateway must expose an OpenAI-compatible endpoint so existing tooling (LangChain,
LlamaIndex, Cursor, etc.) works without code changes:

- Model Registry
The Model Registry is the source of truth for every model available in your private cluster. It stores
metadata, capabilities, pricing (cost-per-token), health status, and endpoint locations.
Schema example (PostgreSQL):
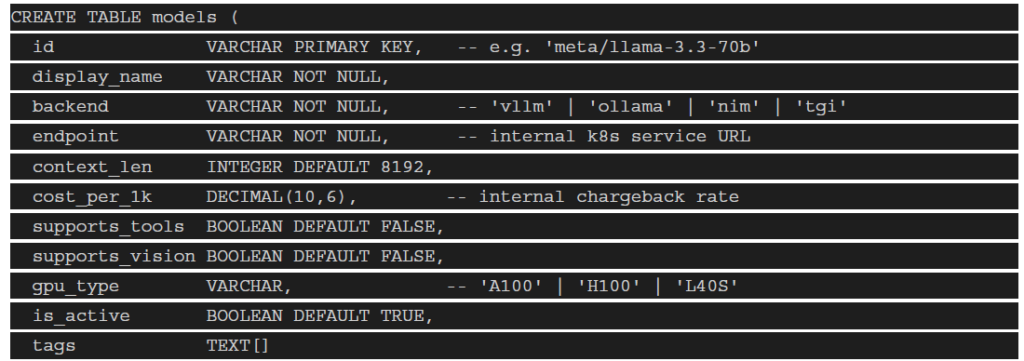
The registry should expose a REST API (GET /v1/models) returning the same JSON schema as
OpenRouter’s models endpoint — enabling zero-code integration with existing tooling.
3. Intelligent Routing Engine
This is the brain of the system. The routing engine receives a normalized request and decides which
backend model instance should serve it. It runs in milliseconds and consults multiple signals.
Routing logic (Python pseudocode):
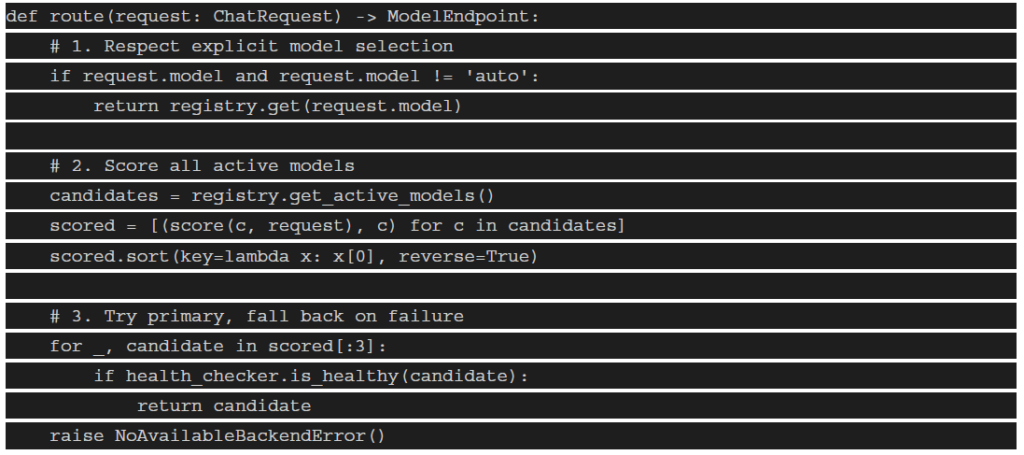
Scoring factors to implement:
- Latency score: Current p95 response time from Prometheus metrics
- Capacity score: (1 – GPU_util%) × weight — prefer underutilized GPUs
- Cost score: 1/cost_per_1k — prefer cheaper backends for simple tasks
- Capability score: Does this model support tools/vision if the request needs it
- Affinity score: Route coding tasks to code-specialized models (DeepSeek, Qwen-Coder)
4. Provider Adapter Layer
Each AI serving backend has a slightly different API contract. The adapter layer translates between your
unified OpenAI schema and each backend’s native format.
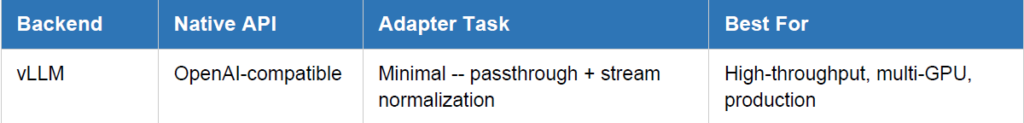
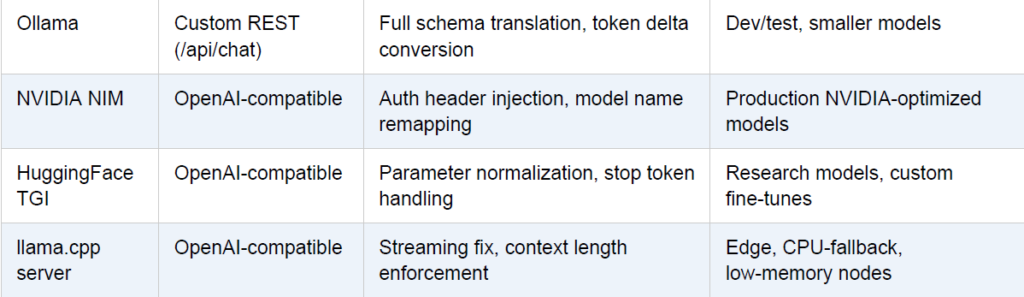
- Streaming: All adapters must normalize SSE (Server-Sent Events) delta format. Backends differ in
how they emit tokens. - Error mapping: Translate backend-specific errors (CUDA OOM, context exceeded) into standard
HTTP 429/500 codes. - Context enforcement: Reject requests exceeding a model’s max context before hitting the backend
to avoid wasted compute.
5. Health Checker & Circuit Breaker
Production inference endpoints fail. GPUs OOM. Pods restart. The health checker continuously probes
each backend and updates routing availability — preventing the router from sending traffic to degraded
instances.
Health check implementation:
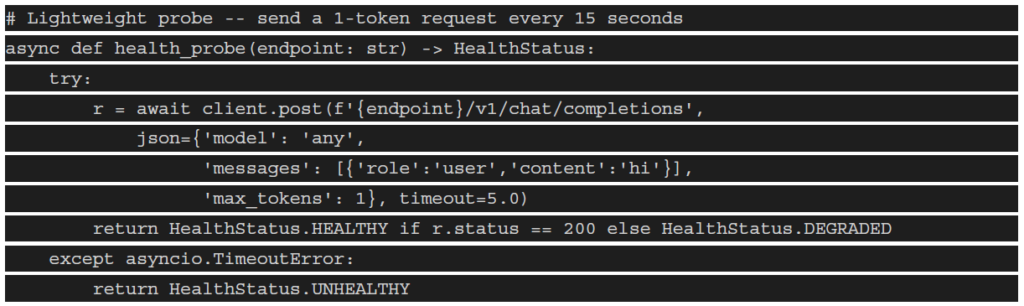
Store health state in Redis for sub-millisecond routing decisions. Never query the database during the hot
routing path.
6. Middleware & Plugin Layer
One of OpenRouter’s most powerful features is its middleware — capabilities layered on top of any model
without changing the model itself. In your private router, this is how you extend all models uniformly.
Middleware pipeline (request flow):
Incoming Request -> [PII Scan] -> [Cache Check] -> [RAG Inject] -> Backend
Backend Response -> [Guardrails] -> [Cache Store] -> [Usage Log] -> Client
Priority middleware to implement first:
- Semantic Cache: Hash normalized prompts and cache embeddings in Redis. Return cached
responses for semantically similar queries — dramatic cost savings for repeated workflows. - PII Redactor: Scan prompts for credit cards, SSNs, emails, named entities using spaCy or Microsoft
Presidio before sending to any model. - System Prompt Manager: Allow teams to register named system prompts centrally. Teams
reference them by ID rather than duplicating 2000-token prompts in every request.
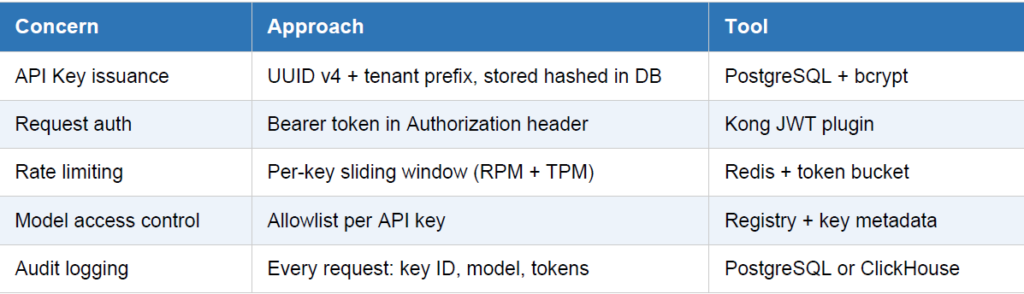
7. Authentication & Multi-Tenancy
Enterprise deployments serve multiple teams, projects, and cost centers. Your router must enforce
namespace isolation, per-tenant rate limits, and chargeback visibility.
8. Usage Tracking & Chargeback
Even when there’s no per-token dollar cost (you own the hardware), tracking usage is critical for capacity
planning, cost allocation, and abuse prevention.
Usage event schema (write on every completed request):
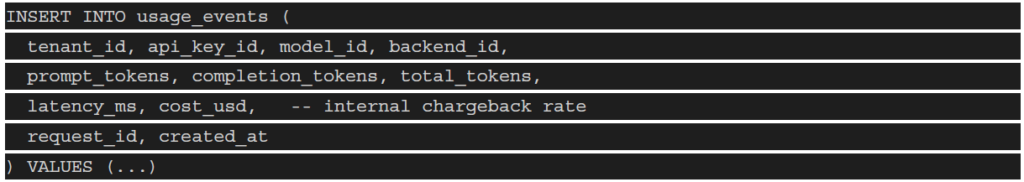
Expose a dashboard (Grafana or custom React UI) showing token consumption per team, model
utilization breakdown, cost allocation per project, P95/P99 latency per model, and error rates.
9. Observability Stack
Without observability, you’re flying blind. The private router must emit metrics, traces, and logs that your
ops team can act on in real time.
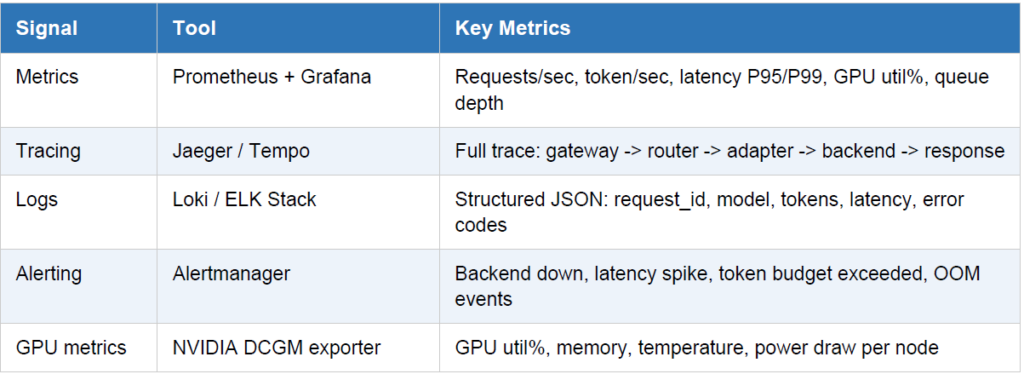
Instrument your router to emit an OpenTelemetry (OTEL) span for every hop. This gives you
end-to-end trace visibility from the client SDK all the way to the GPU kernel — invaluable for
debugging latency anomalies in multi-model workflows.
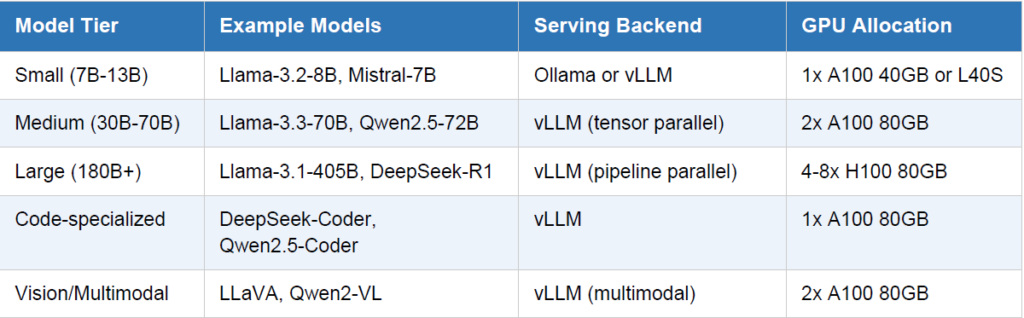
10. GPU Inference Cluster
The compute layer is where the actual inference happens. On a Kubernetes private cluster with NVIDIA
GPUs, your serving setup typically looks like this:
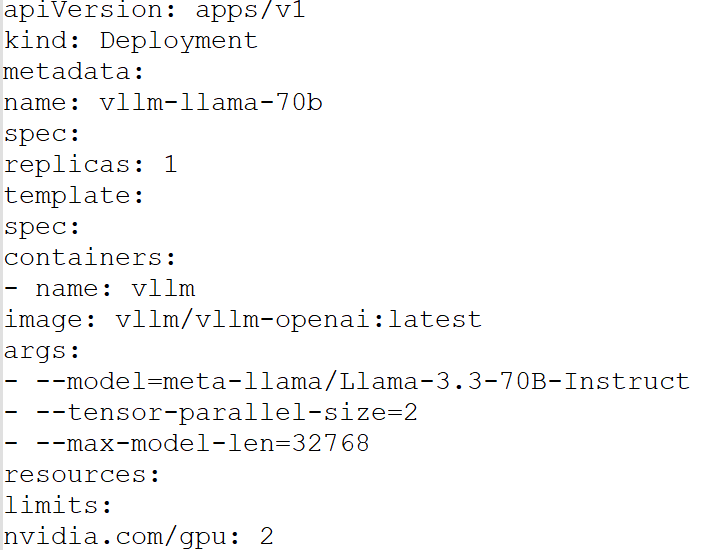
vLLM deployment example (Kubernetes manifest):
Recommended Tech Stack Summary
Security Considerations
A private router is security-critical infrastructure. It sits between all your AI workloads and your GPU
compute. These considerations are non-negotiable:
- mTLS everywhere: Use mutual TLS between the gateway, router, and all backend adapters. NSX-T
micro-segmentation or Istio service mesh can enforce this at the platform level. - No prompt logging by default: Log token counts and metadata, not prompt content. Make full
prompt logging an explicit opt-in with appropriate data governance controls. - Model isolation: Each model deployment runs in its own namespace with NetworkPolicy rules.
Cross-namespace traffic is denied unless explicitly allowed. - GPU node hardening: Disable SSH on GPU nodes. All access through Kubernetes API + RBAC
only. Patch CUDA drivers on a regular schedule. - API key rotation: Implement automatic key rotation policies. Support emergency revocation.
- Egress control: Firewall rules ensuring model inference nodes have zero internet egress. Model
weights pulled from internal artifact registry (Harbor), not Hugging Face directly.
Business Opportunity: Managed Private AI Router as a Service
Once you have built and battle-tested a private LLM router for your own organization, you have something genuinely rare — a production-grade, enterprise-hardened AI infrastructure platform. That is the foundation for a high-value managed service business serving multiple enterprise clients simultaneously.
Think of it as becoming the private OpenRouter for your industry vertical or region: hosting, operating,
and continuously improving the routing layer so enterprises don’t have to build it themselves. This section outlines the business model, service tiers, orchestration use cases, and the multi-tenant architecture that makes it commercially viable.
MARKET: Market Context
Enterprises want sovereign AI but lack the platform engineering talent to build it. Managed
service providers who can offer a turnkey private LLM router — with SLAs, compliance
assurances, and onboarding support — can command significant contract values while operating
shared GPU infrastructure at scale.
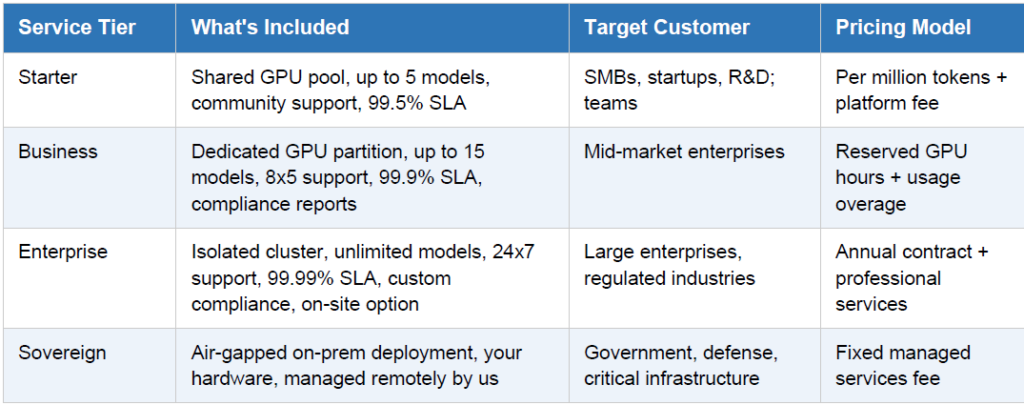
- The Managed Service Model
The core value proposition is simple: you operate the complexity so your enterprise clients don’t have to.
Each client gets a logically isolated tenant on your shared (or dedicated) GPU infrastructure, accessed
through their own private API endpoint and API keys, with full data isolation guarantees.
2. Multi-Enterprise Architecture
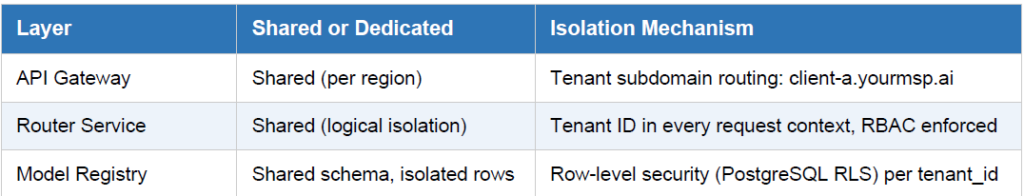
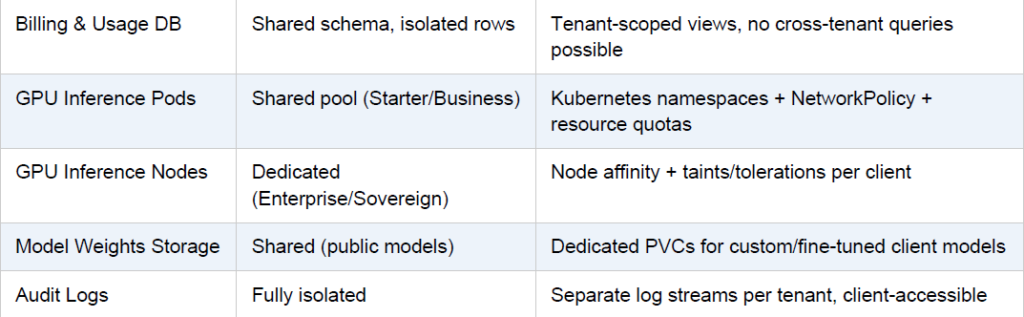
The key architectural challenge for a managed service is strong multi-tenant isolation while still sharing the expensive GPU compute efficiently. Here is how the layers split between shared and dedicated:
SECURITY: Data Guarantee
No enterprise client’s prompts, completions, or usage metadata are ever accessible to another
tenant. Enforce this at the database layer (row-level security), at the network layer
(NetworkPolicy), and contractually (DPA/BAA). Audit this separation quarterly.
3. Enterprise Use Cases Built on the Platform
Beyond raw API access, the real managed service value comes from helping enterprises build production
AI workflows on top of your router using orchestration tools. Below are the highest-value use cases by
industry vertical:
3a. RAG-Powered Knowledge Bases (All Verticals)
Every enterprise has unstructured document repositories — SharePoint, Confluence, internal wikis, PDF
archives. A managed RAG pipeline built on your router lets employees query this knowledge in natural
language without any data leaving the corporate perimeter.
Orchestration stack:
- LlamaIndex or LangChain: Document ingestion, chunking, and retrieval pipeline
- Qdrant or Weaviate (self-hosted): Private vector store for embeddings
- Your router: Serves both the embedding model and the generation model via one API
- Apache Airflow: Scheduled re-ingestion as documents are updated
3b. Code Review & Developer Assist (Technology / FSI)
Route coding tasks automatically to code-specialized models (DeepSeek-Coder, Qwen2.5-Coder) while
keeping all proprietary source code within the enterprise network. Integrate directly into GitLab CI/CD or
GitHub Enterprise via a webhook adapter.
Orchestration stack:
- GitLab CI/CD webhooks: Trigger reviews on merge request events
- Your router (model affinity tag: ‘code’): Automatically routes to best code model
- Prefect or Temporal: Workflow orchestration for multi-step review pipelines
- Redis pub/sub: Async result delivery back to the developer’s IDE
3c. Compliance Document Analysis (Legal / Healthcare / Finance)
Regulated enterprises need to analyze contracts, medical records, and financial filings without sending
sensitive documents to public APIs. A managed document intelligence pipeline on your router provides
this with full audit trails.
Orchestration stack:
- Apache Tika or Unstructured.io: Document parsing and normalization
- Your router middleware (PII redactor enabled): Auto-scrub before model sees data
- LangGraph: Multi-step reasoning workflows — extract, classify, summarize, flag
- PostgreSQL: Store structured outputs for downstream reporting and audit
3d. Multi-Agent Automation (Operations / Supply Chain)
Enterprises are moving beyond single-turn Q&A; to autonomous agents that can plan, tool-call, and
execute multi-step workflows. Your router becomes the inference backbone for agent frameworks that
need reliable, fast, private LLM access.
Orchestration stack:
- LangGraph or CrewAI: Multi-agent coordination (planner, executor, critic agents)
- Your router: Routes each agent’s LLM call to the optimal model — fast model for planning, powerful
model for reasoning - Temporal or Prefect: Durable execution, retry logic, and human-in-the-loop approval steps
- Apache Kafka: Event streaming between agents in high-throughput pipelines
3e. Customer-Facing AI Products (Retail / Telecom / BFSI)
Enterprises building their own AI-powered products (chatbots, copilots, recommendation engines) need a
stable, SLA-backed inference API. Your managed router becomes their internal ‘model provider’ —
shielding their product teams from infrastructure complexity.
Orchestration stack:
- Your router API: The only LLM endpoint their product team integrates
- Redis semantic cache: Cache common customer query patterns — dramatically reduces
per-session cost - Grafana dashboards (tenant-scoped): Product team can monitor their own usage and latency
- Canary routing: A/B test new models on 5% of traffic before full rollout
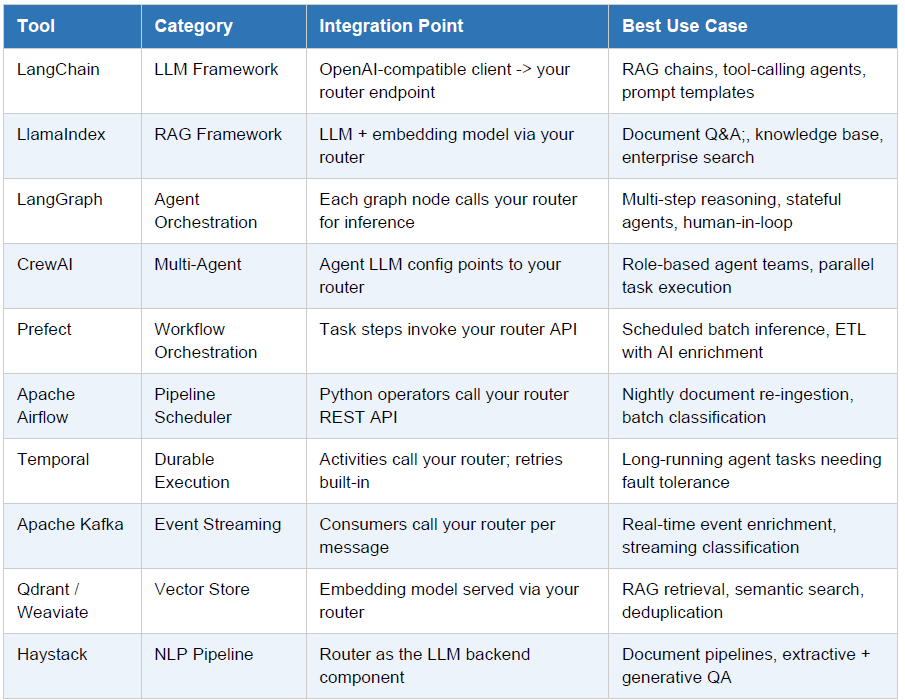
4. Orchestration Tools Integration Matrix
Below is a reference matrix of orchestration tools and how they integrate with your managed router
platform:
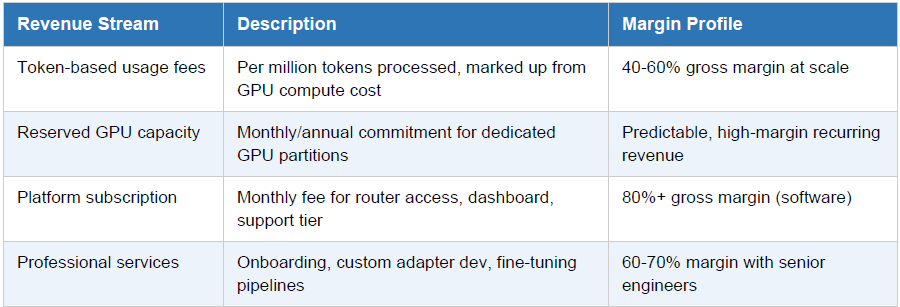
5. Revenue Model & Unit Economics
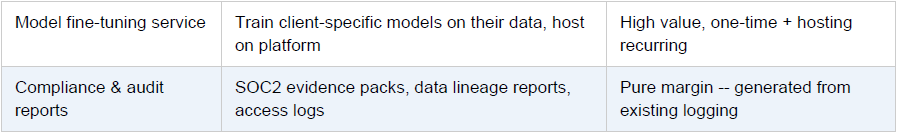
The managed service business model benefits from significant operating leverage — GPU infrastructure is
the primary cost, and it becomes more efficient as utilization increases across tenants.
Conclusion: Building a Secure and Scalable Private LLM Router
As enterprises adopt artificial intelligence, they need greater control over how their applications access and use large language models.
Public AI services provide convenience and flexibility. However, organizations handling sensitive information may require stronger control over data processing, model deployment, and infrastructure security.
A Private LLM Router offers a practical approach to managing these requirements.
By providing a unified API, organizations can connect multiple self-hosted language models through a single interface.
For example, a private router can integrate vLLM, Ollama, NVIDIA NIM, and other supported inference platforms. As a result, developers can access different models without managing separate integrations for every backend.
In addition, intelligent routing can help organizations select suitable models based on performance, availability, cost, and application requirements.
Security and Infrastructure Control
Security remains a major consideration for enterprise AI deployment.
Therefore, organizations should implement strong authentication, network segmentation, encryption, and access controls.
Furthermore, monitoring tools can help teams track model performance, GPU utilization, request latency, and service availability.
These capabilities are especially important for organizations operating in regulated industries.
However, private deployment does not automatically guarantee security or regulatory compliance. Enterprises must still establish appropriate governance, testing, monitoring, and operational controls.
Opportunities for Managed Private AI Services
Beyond internal applications, private LLM routing can also support new business opportunities.
For example, managed service providers can offer private AI infrastructure to organizations that lack dedicated AI platform engineering teams.
These services may support document analysis, enterprise knowledge assistants, code review, customer support, and workflow automation.
In addition, a managed private LLM platform can provide centralized model management, monitoring, and usage tracking.
However, providers must carefully plan infrastructure capacity, customer isolation, service-level agreements, and operating costs.
Final Thoughts
Building a private LLM router involves more than connecting multiple AI models.
It requires a reliable architecture that combines intelligent routing, secure API access, GPU infrastructure, observability, and operational management.
Ultimately, the goal is to make enterprise AI applications easier to manage while maintaining control over security, performance, and infrastructure.
Whether your organization is building an internal AI platform or exploring managed AI services, a private LLM router can provide a flexible foundation for future applications.
The best approach is to start with clear business requirements, validate the architecture through testing, and expand as application demand grows.
Ready to Build Your Own Private LLM Infrastructure?
Managing multiple language models does not have to mean managing separate APIs, inconsistent integrations, and complex infrastructure.
A well-designed private LLM router can help you centralize model access, strengthen security controls, and manage AI workloads more efficiently.
Whether you’re deploying vLLM on Kubernetes, building an enterprise AI platform, or exploring managed private AI services, understanding the architecture is the first step.
Explore more practical AI infrastructure guides, deployment strategies, and enterprise networking tutorials on Network Bachelor.
Have you deployed a private LLM platform?
Share your experience, challenges, or architecture questions in the comments.
Planning a Private AI Infrastructure Deployment?
Building a secure enterprise AI environment requires careful planning across networking, cybersecurity, GPU infrastructure, and application integration.
Trezbon Technologies helps organizations evaluate infrastructure requirements and plan technology solutions aligned with their business objectives.
Discuss your private AI infrastructure requirements with our team.
NVIDIA DGX SuperPOD: Build a Mini SuperPOD Lab Step by Step
LLM Quantization with vLLM: PTQ vs QAT Guide
Agentic AI Capacity Planning: Why vLLM Changes the Model
About Author

abhishek
Cloud Platform Lead and AI Infrastructure Architect at e& enterprise, with 12+ years in data center, virtualization, security and AI infrastructure. I design and build private cloud and sovereign AI platforms, working with VMware (NSX-T, vSphere, vSAN, HCX, AVS, SRM), Kubernetes, Terraform and GPU inference infrastructure for LLMs. Previously served Networkers Home (CCIE instructor, trained around 50 CCIEs), VCE/EMC2, Cisco, VMware and Arista across TAC, consulting, design and training. Certifications: CCIE#48639 (Data Center and R&S), VCIX-DCV and NV, CKA, NVIDIA AI Infrastructure, Azure Solutions Architect Expert, Terraform Associate, Palo Alto PCNSE. LinkedIn: https://www.linkedin.com/in/abhishekkunal51/