Discover how AI-powered firewall troubleshooting uses GraphRAG, Neo4j, RAG, and network automation to accelerate root cause analysis and resolve security issues.
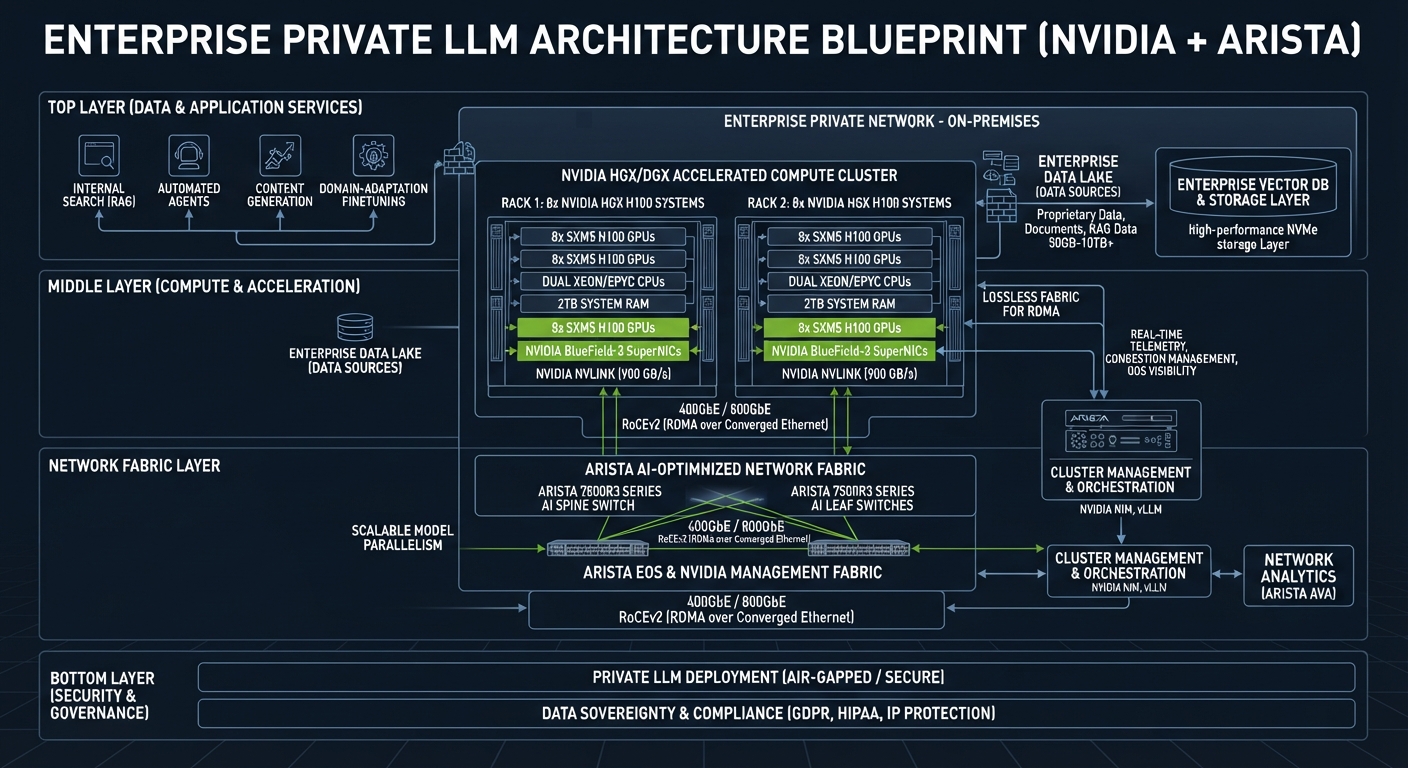
As data sovereignty, regulatory compliance (such as GDPR, HIPAA, and financial frameworks), and intellectual property protection take center stage, enterprises are shifting rapidly from public cloud APIs to private Large Language Model (LLM) deployments. Operating a private LLM means your sensitive corporate data never leaves your infrastructure perimeter. However, building an internal LLM stack is
Explore enterprise private LLM infrastructure architecture, GPU sizing, high-performance networking, security, and deployment best practices for AI workloads.
Part 9 of the Falcon AI workbook series. Parts 5 and 6 confirmed DCGM Exporter and Node Exporter pods were Running — but “Running” isn’t the same as “wired into a dashboard someone actually looks at.” This post closes that gap: full-stack observability for cluster, nodes, GPUs, network, and the application layer from Part 8.
Explore NVIDIA GPU workloads on Kubernetes in Part 8. Learn to build scalable AI platforms, deploy applications, and optimize GPU-powered AI/ML workloads.